Amazon S3
Writes batches of records as objects in an S3 bucket, or a bucket in an S3-compatible store.
Example
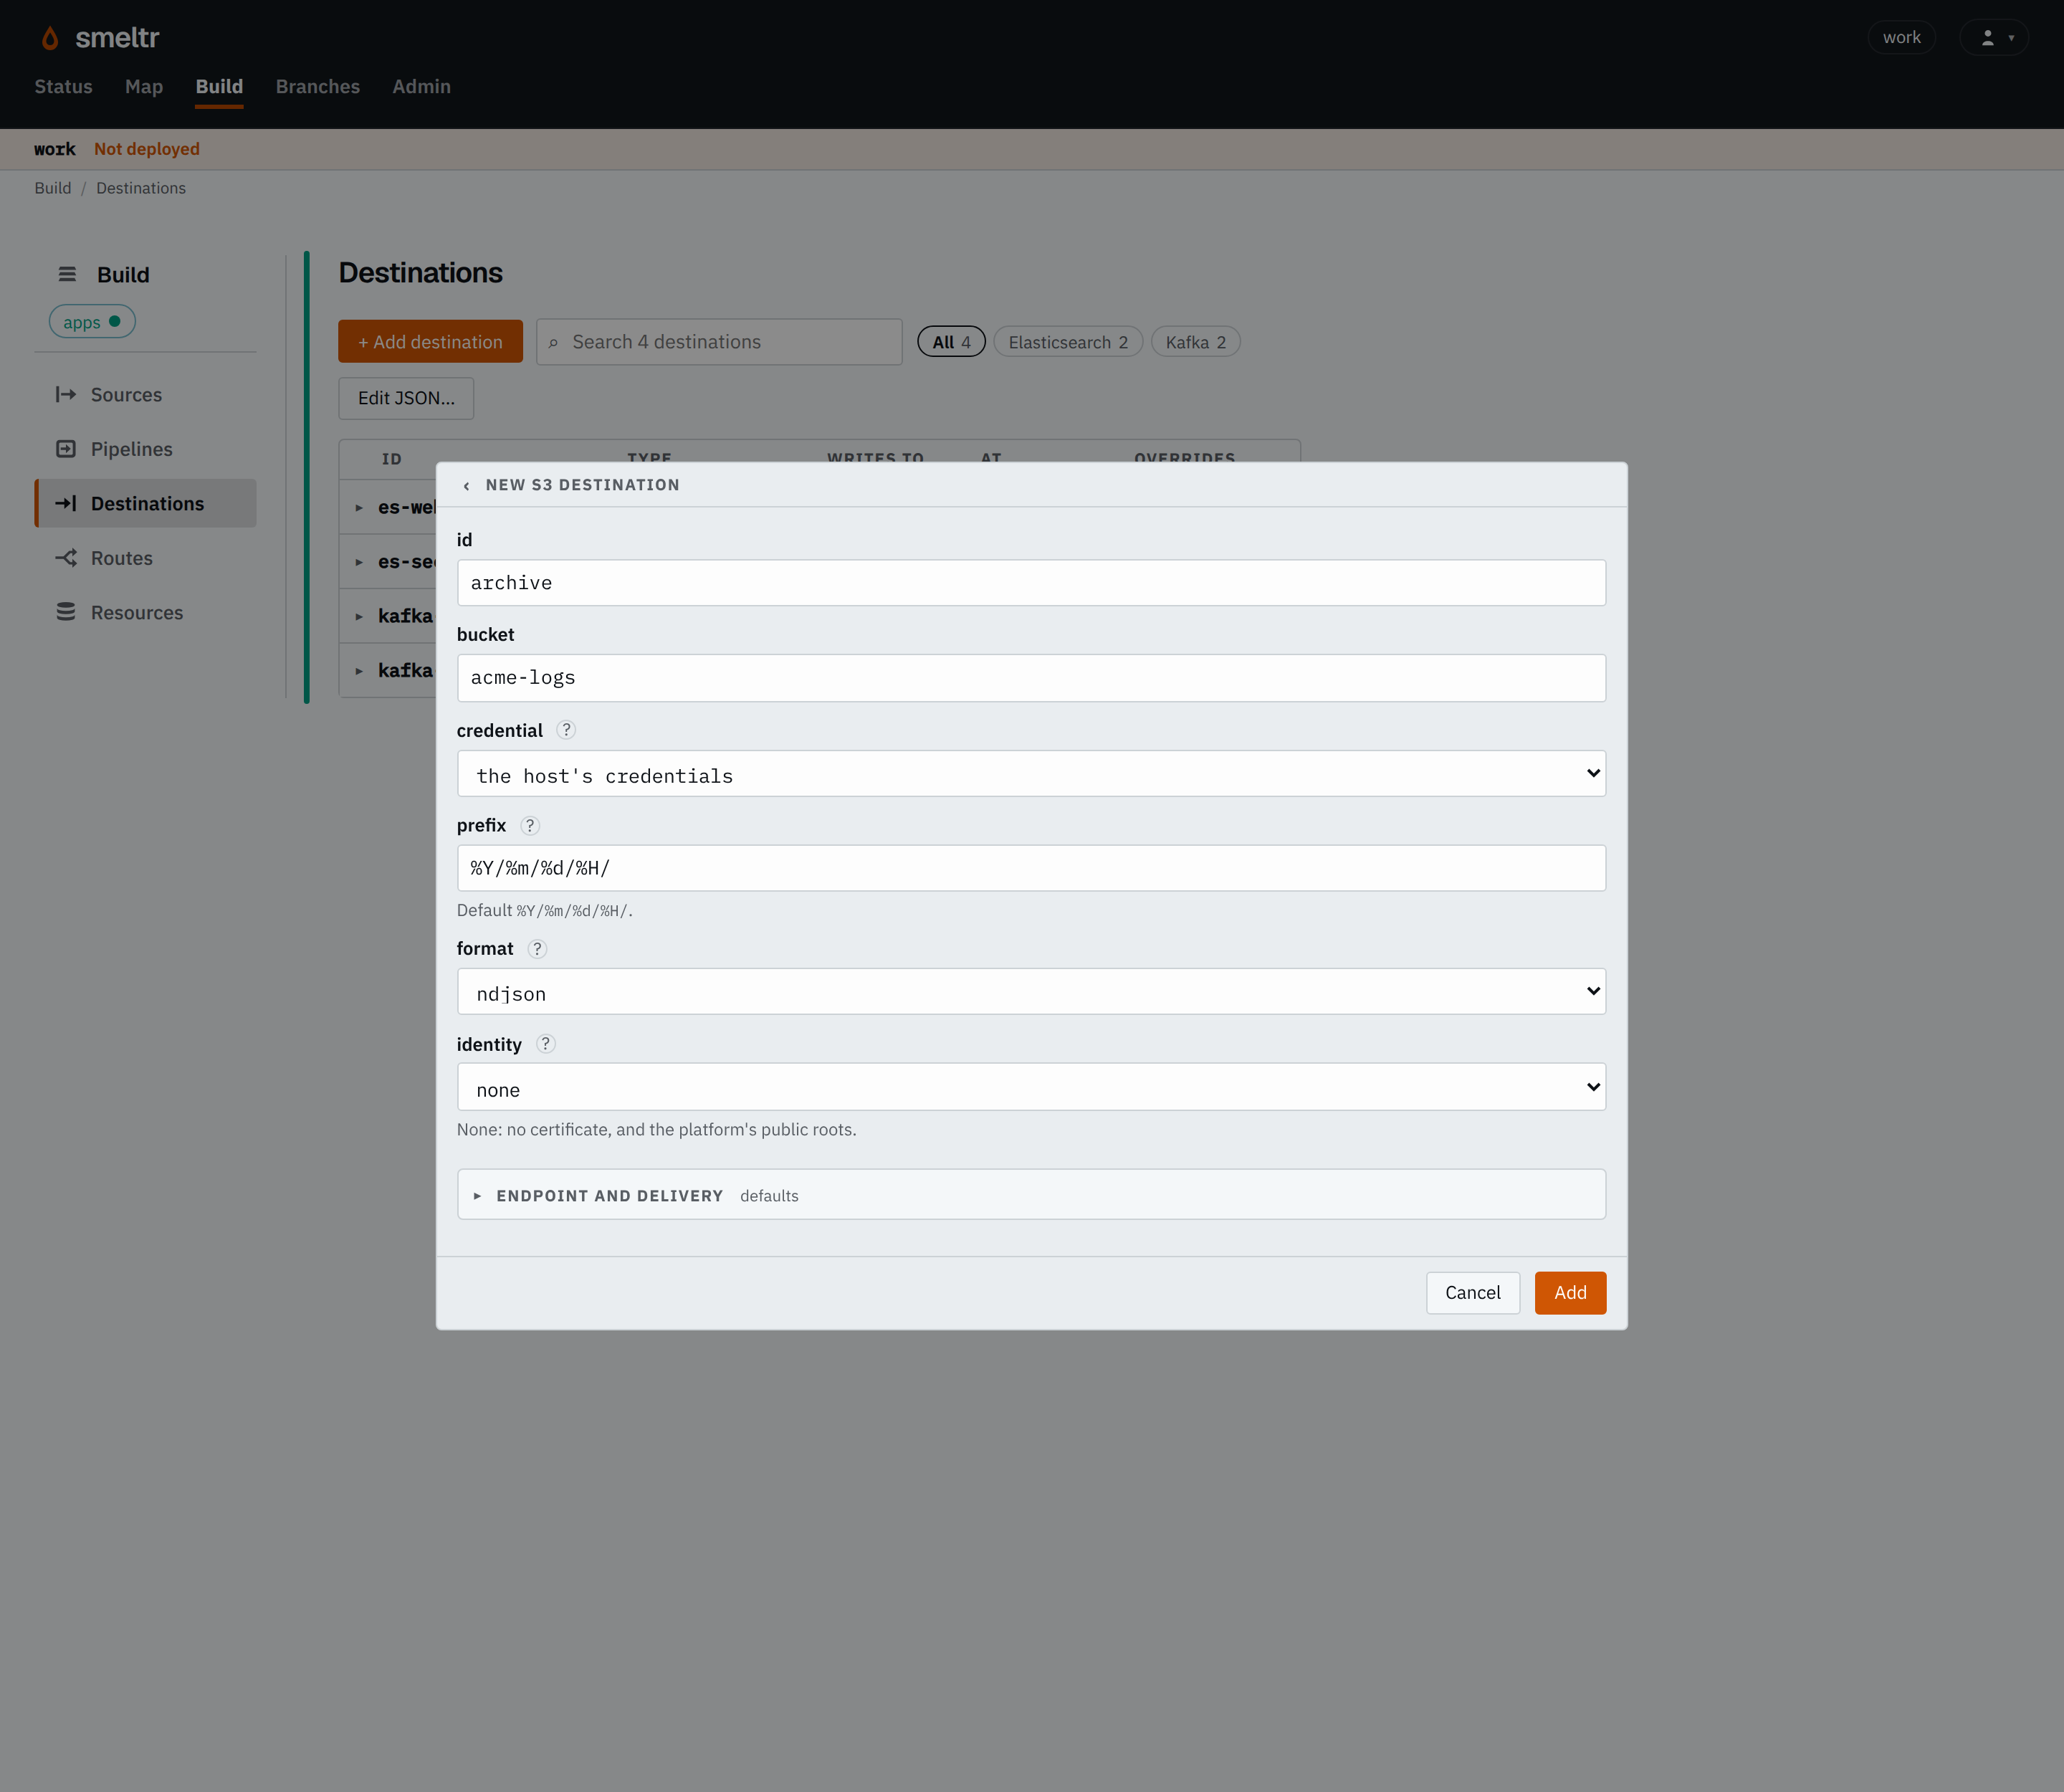
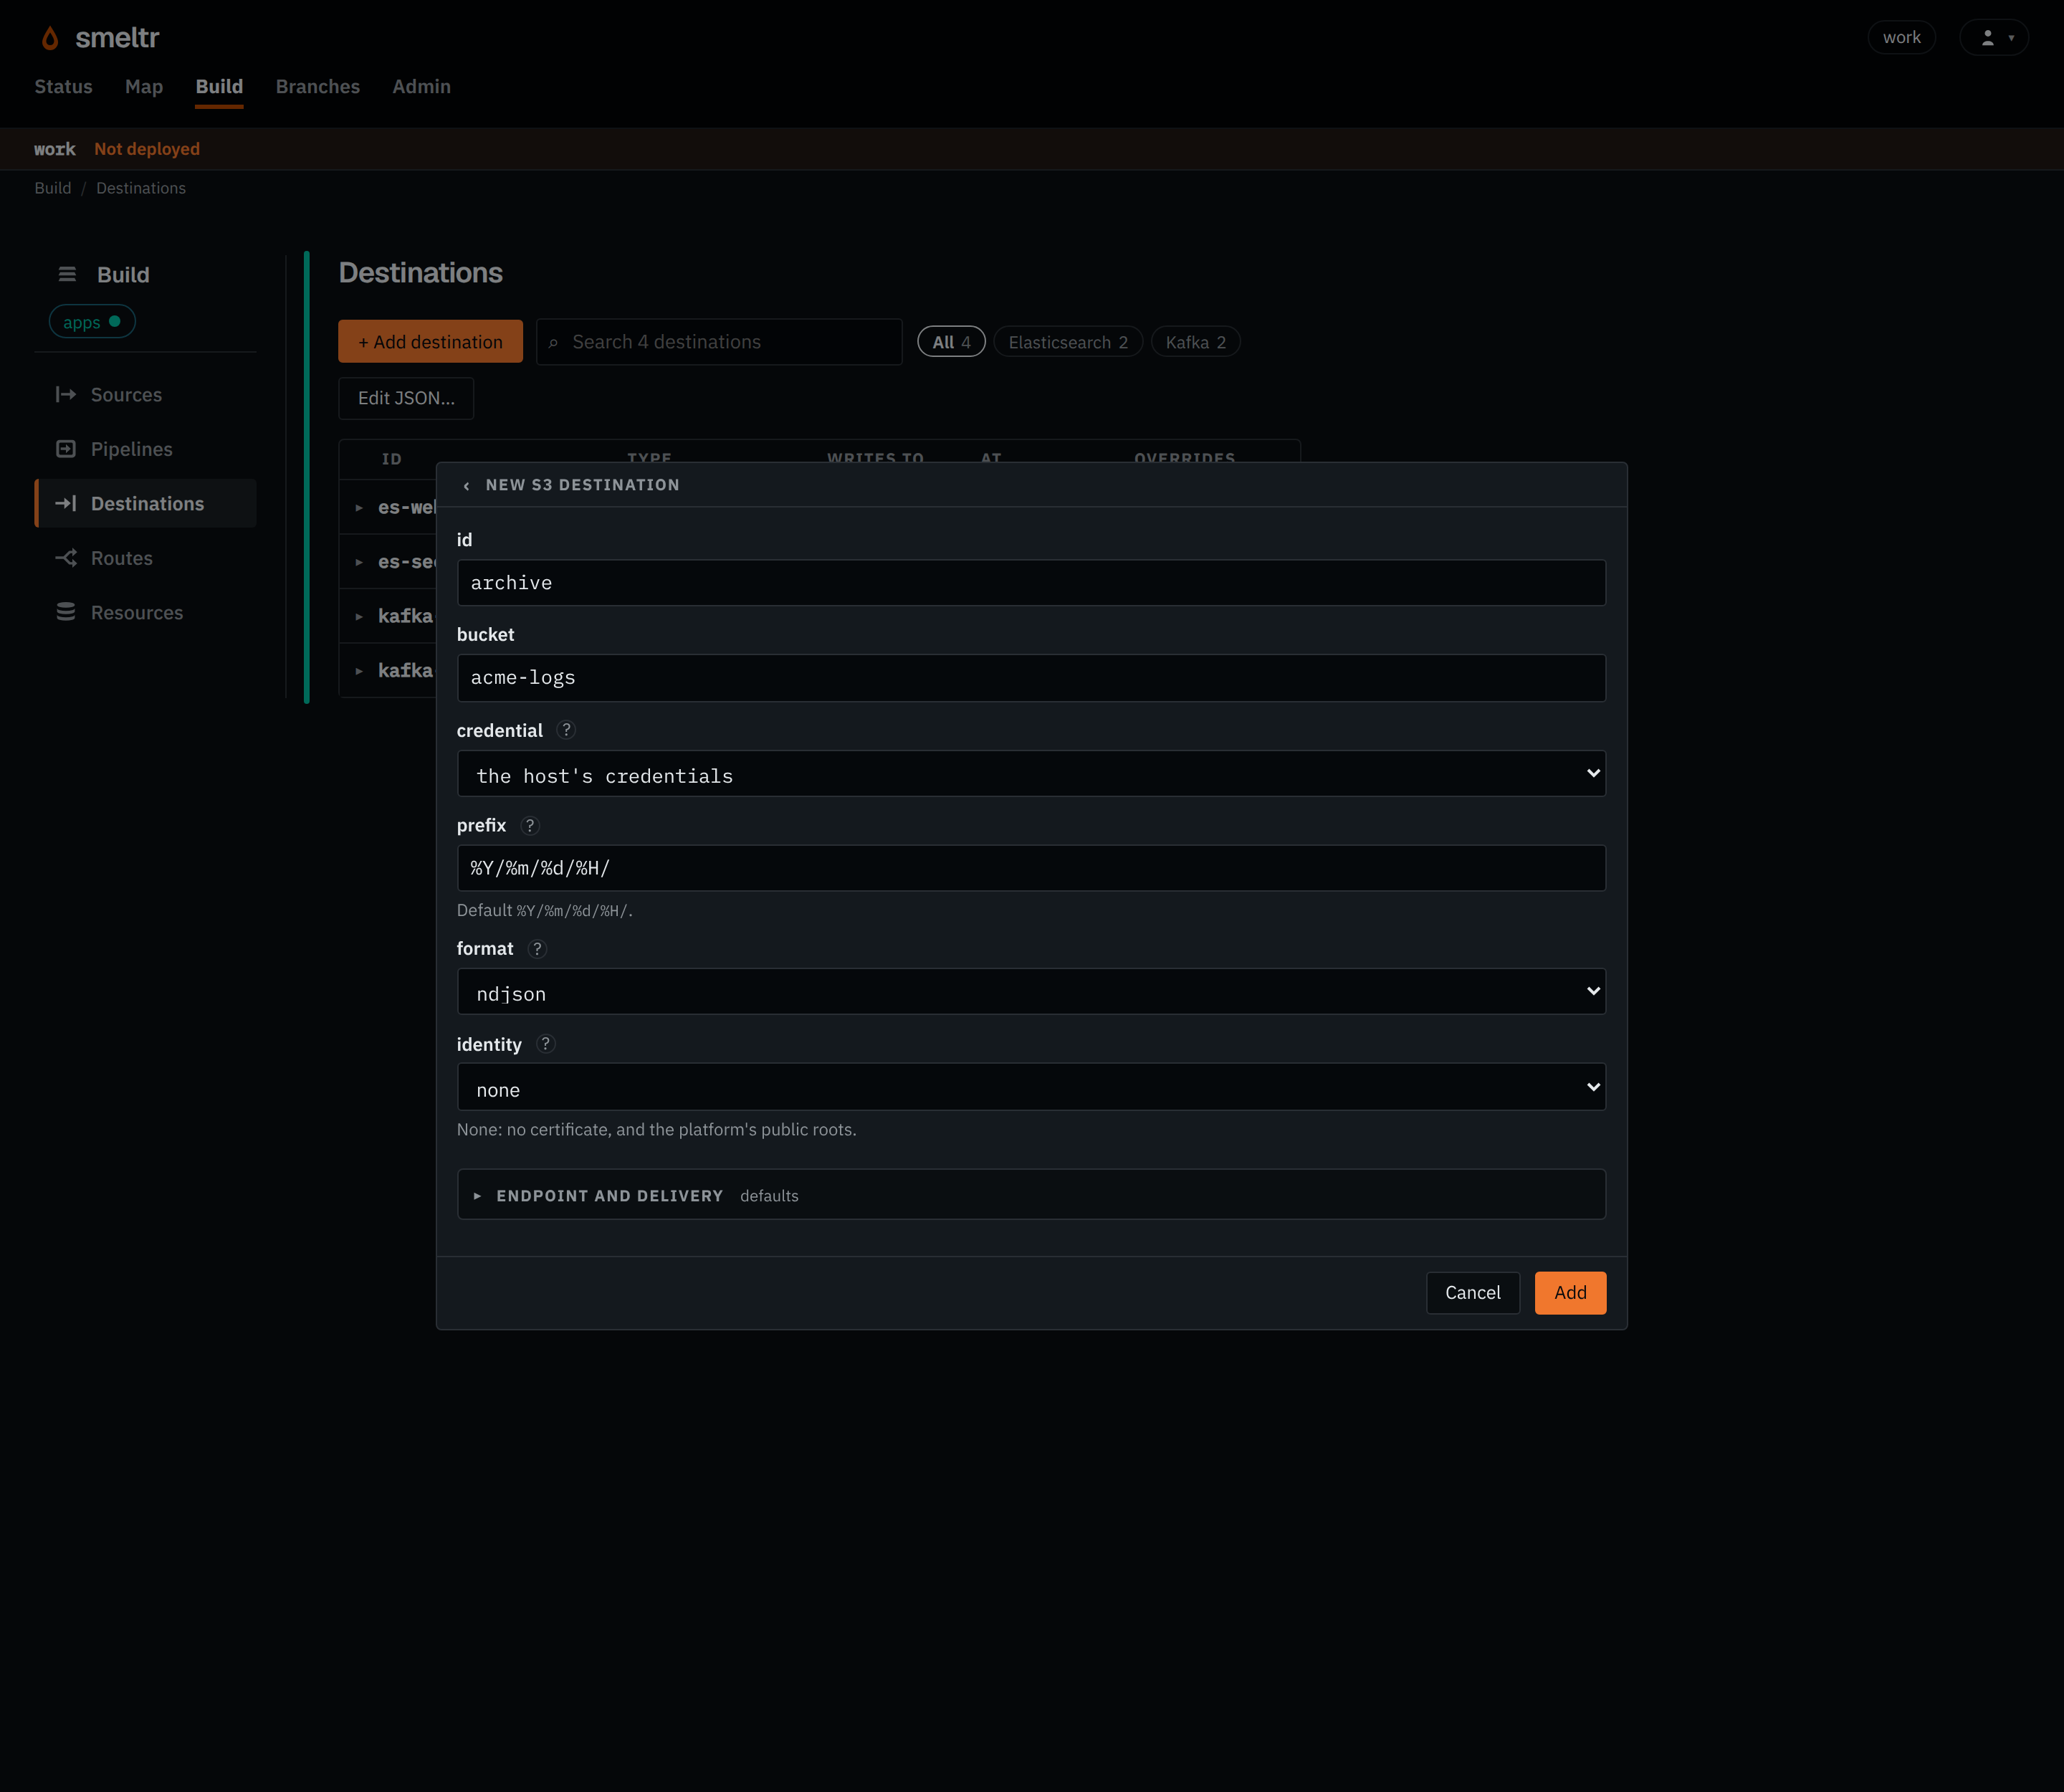
Writes with the worker host's AWS credentials.
{
  "id": "archive",
  "type": "s3",
  "bucket": "acme-logs",
  "region": "us-east-2"
}
Before you start
- Create the bucket.
- Give the identity the destination writes as permission to put objects in the bucket (
s3:PutObject). See S3 policy examples. WithkmsKeyId, it also needs to use that key; see SSE-KMS. - Choose how it signs in. With no access key, it uses the worker host's own AWS credentials, such as an instance role; see AWS credential providers. Otherwise put the access key's id and secret in credentials.
- For a bucket in another account, give a role to assume in
roleArn, and its external id if it requires one. See cross-account roles.
Settings
It also takes the settings every destination takes.
bucket string required
The bucket.
acme-logsacme-logs-111122223333accessKeyId credential default the host's credentials
The credential holding the access key's id. Set both accessKeyId and secretAccessKey, or neither.
AWS_ACCESS_KEY_ID{"secret": "aws-access-key-id","version": 1}secretAccessKey credential default the host's credentials
The credential holding the access key's secret.
AWS_SECRET_ACCESS_KEY{"secret": "aws-secret-access-key","version": 1}prefix string default %Y/%m/%d/%H/
What each object's key starts with, for a record with no __destination.prefix. %Y, %m, %d, %H and %M are the write time, UTC, and no other % is allowed. A key never starts with /.
events/%Y/%m/%d/firewall/dt=%Y-%m-%d/hour=%H/acme/audit/format string default ndjson
What each object holds.
ndjson- Writes one JSON document per line.
json- Writes one JSON array of every record.
parquet- Writes one Parquet file.
avro- Writes one Avro file.
csv- Writes one CSV file.
text- Writes one line of text per record, from
field. bytes- Writes each source record's bytes as read, before pipeline processing, one per line:
__source.bytesunlessfieldnames anotherbytesfield.
field string default _raw for text, __source.bytes for bytes
The field each line of a text or bytes object holds. Only with format text or bytes.
messagenewlines string default escape
What a bytes object does with a record holding a line break. Only with format bytes.
escape- Writes
\, newline and carriage return as\\,\nand\r, which a source with framingescapedLinesreverses. refuse- Refuses the record.
identity identity default none
The connection identity it connects under, for a private CA or a client certificate.
store-clientcorp-proxyAdvanced: Endpoint and delivery
region string default the host's, else us-east-1
The bucket's region.
us-east-2eu-west-1ap-southeast-2endpoint string default the host's, else AWS
An S3-compatible service's address. Without an access key, the worker host's AWS settings, such as AWS_ENDPOINT_URL, come first.
https://minio.example.com:9000https://10.0.8.20:9000roleArn string default none
A role to assume, for a bucket in another account.
arn:aws:iam::111122223333:role/smeltr-writerarn:aws:iam::111122223333:role/service-role/smeltr-writerexternalId string default none
The external id the role requires. Only with roleArn.
smeltracme-7f3c2aauthEndpoint string default the region's own
Where the role in roleArn is assumed. Only with roleArn.
https://sts.us-east-2.amazonaws.comhttps://sts-fips.us-east-1.amazonaws.comkmsKeyId string default none
The KMS key each object is encrypted under.
arn:aws:kms:us-east-2:111122223333:key/1234abcd-12ab-34cd-56ef-1234567890abarn:aws:kms:us-east-2:111122223333:alias/smeltr-logscompression string default gzip
How it compresses each object. A parquet object compresses each column inside the file instead, and its key ends with .parquet whatever the compression. An avro file compresses inside the file, and its key ends with .avro. Its gzip is Avro's deflate. Avro has no lz4.
none- Writes it uncompressed. The key ends with the format's own extension, such as
.ndjson. gzip- Compresses it with gzip and appends
.gzto the key, such as.ndjson.gz. snappy- Compresses it with framed Snappy and appends
.szto the key, such as.ndjson.sz. lz4- Compresses it with framed LZ4 and appends
.lz4to the key, such as.ndjson.lz4. zstd- Compresses it with Zstandard and appends
.zstto the key, such as.ndjson.zst.
storageClass string default the bucket's own
The class each object is stored in, one of S3's own: STANDARD, REDUCED_REDUNDANCY, STANDARD_IA, ONEZONE_IA, INTELLIGENT_TIERING, GLACIER, GLACIER_IR, DEEP_ARCHIVE or SNOW.
STANDARD_IAINTELLIGENT_TIERINGGLACIER_IRinFlight integer default 4
How many parts of one file upload at once. 1 to 64.
812maxObjectBytes size default 64 MiB
The largest file it puts in the bucket, compressed. Set it to what the tools that read the bucket handle best. 64 KiB to 64 GiB.
128 MiB2 GiB32 MBbufferBytes size default 256 MiB
Memory it may use on each worker for records not yet in the bucket. Files are finished early when it fills, so files reach maxObjectBytes only when it holds that many records before compression. 4 MiB to 32 TiB.
1 GiB4 GiBstallAfterSecs integer default 30
Seconds one call to the store, or one finishing of the files, may take before it counts as stalled. 1 to 120, and at least 15 on SFTP.
60120fileIntervalSecs integer default 60
The longest records wait, in seconds, before they land in the bucket. A longer wait makes larger files; records are acknowledged only once they land, so a source is held open up to this long, and after a crash reads that much again. 5 to 3600.
30240Fields it reads
| Field | Type | Holds |
|---|---|---|
__destination.prefix | str | What an S3, Google Cloud Storage or Azure Blob Storage destination's object key starts with, taken as it is. Null means the destination's own prefix, with its time placeholders filled in. |
How it works
The destination keeps one object open per prefix, and for Parquet, Avro and CSV per record type
of the routes feeding it, across batches, named <prefix><random id>.<extension>, and finishes it when it reaches maxObjectBytes on disk, when fileIntervalSecs passes, when bufferBytes fills on the worker, or when a 65th object opens and this one
was written least recently. A batch is acknowledged once every object holding its records has landed.
Two objects never share a key, so records written again after a failure make new objects.
Verify
Send a record with a unique marker through the source, then list the bucket under the prefix for a new object and look for the marker in it.
Troubleshooting
- Access denied
- Check that the identity may put objects in the bucket, and may use the KMS key when
kmsKeyIdis set.